We ran three new models through Vending-Bench 2 and Vending-Bench Arena: Claude Opus 5.5, GPT-6 Sol and Grok 4.7. Each ran six times on its own, where a model gets $500 and a vending machine and has one simulated year to make as much money as it can, and the three then competed in four arena games, running machines at the same location.
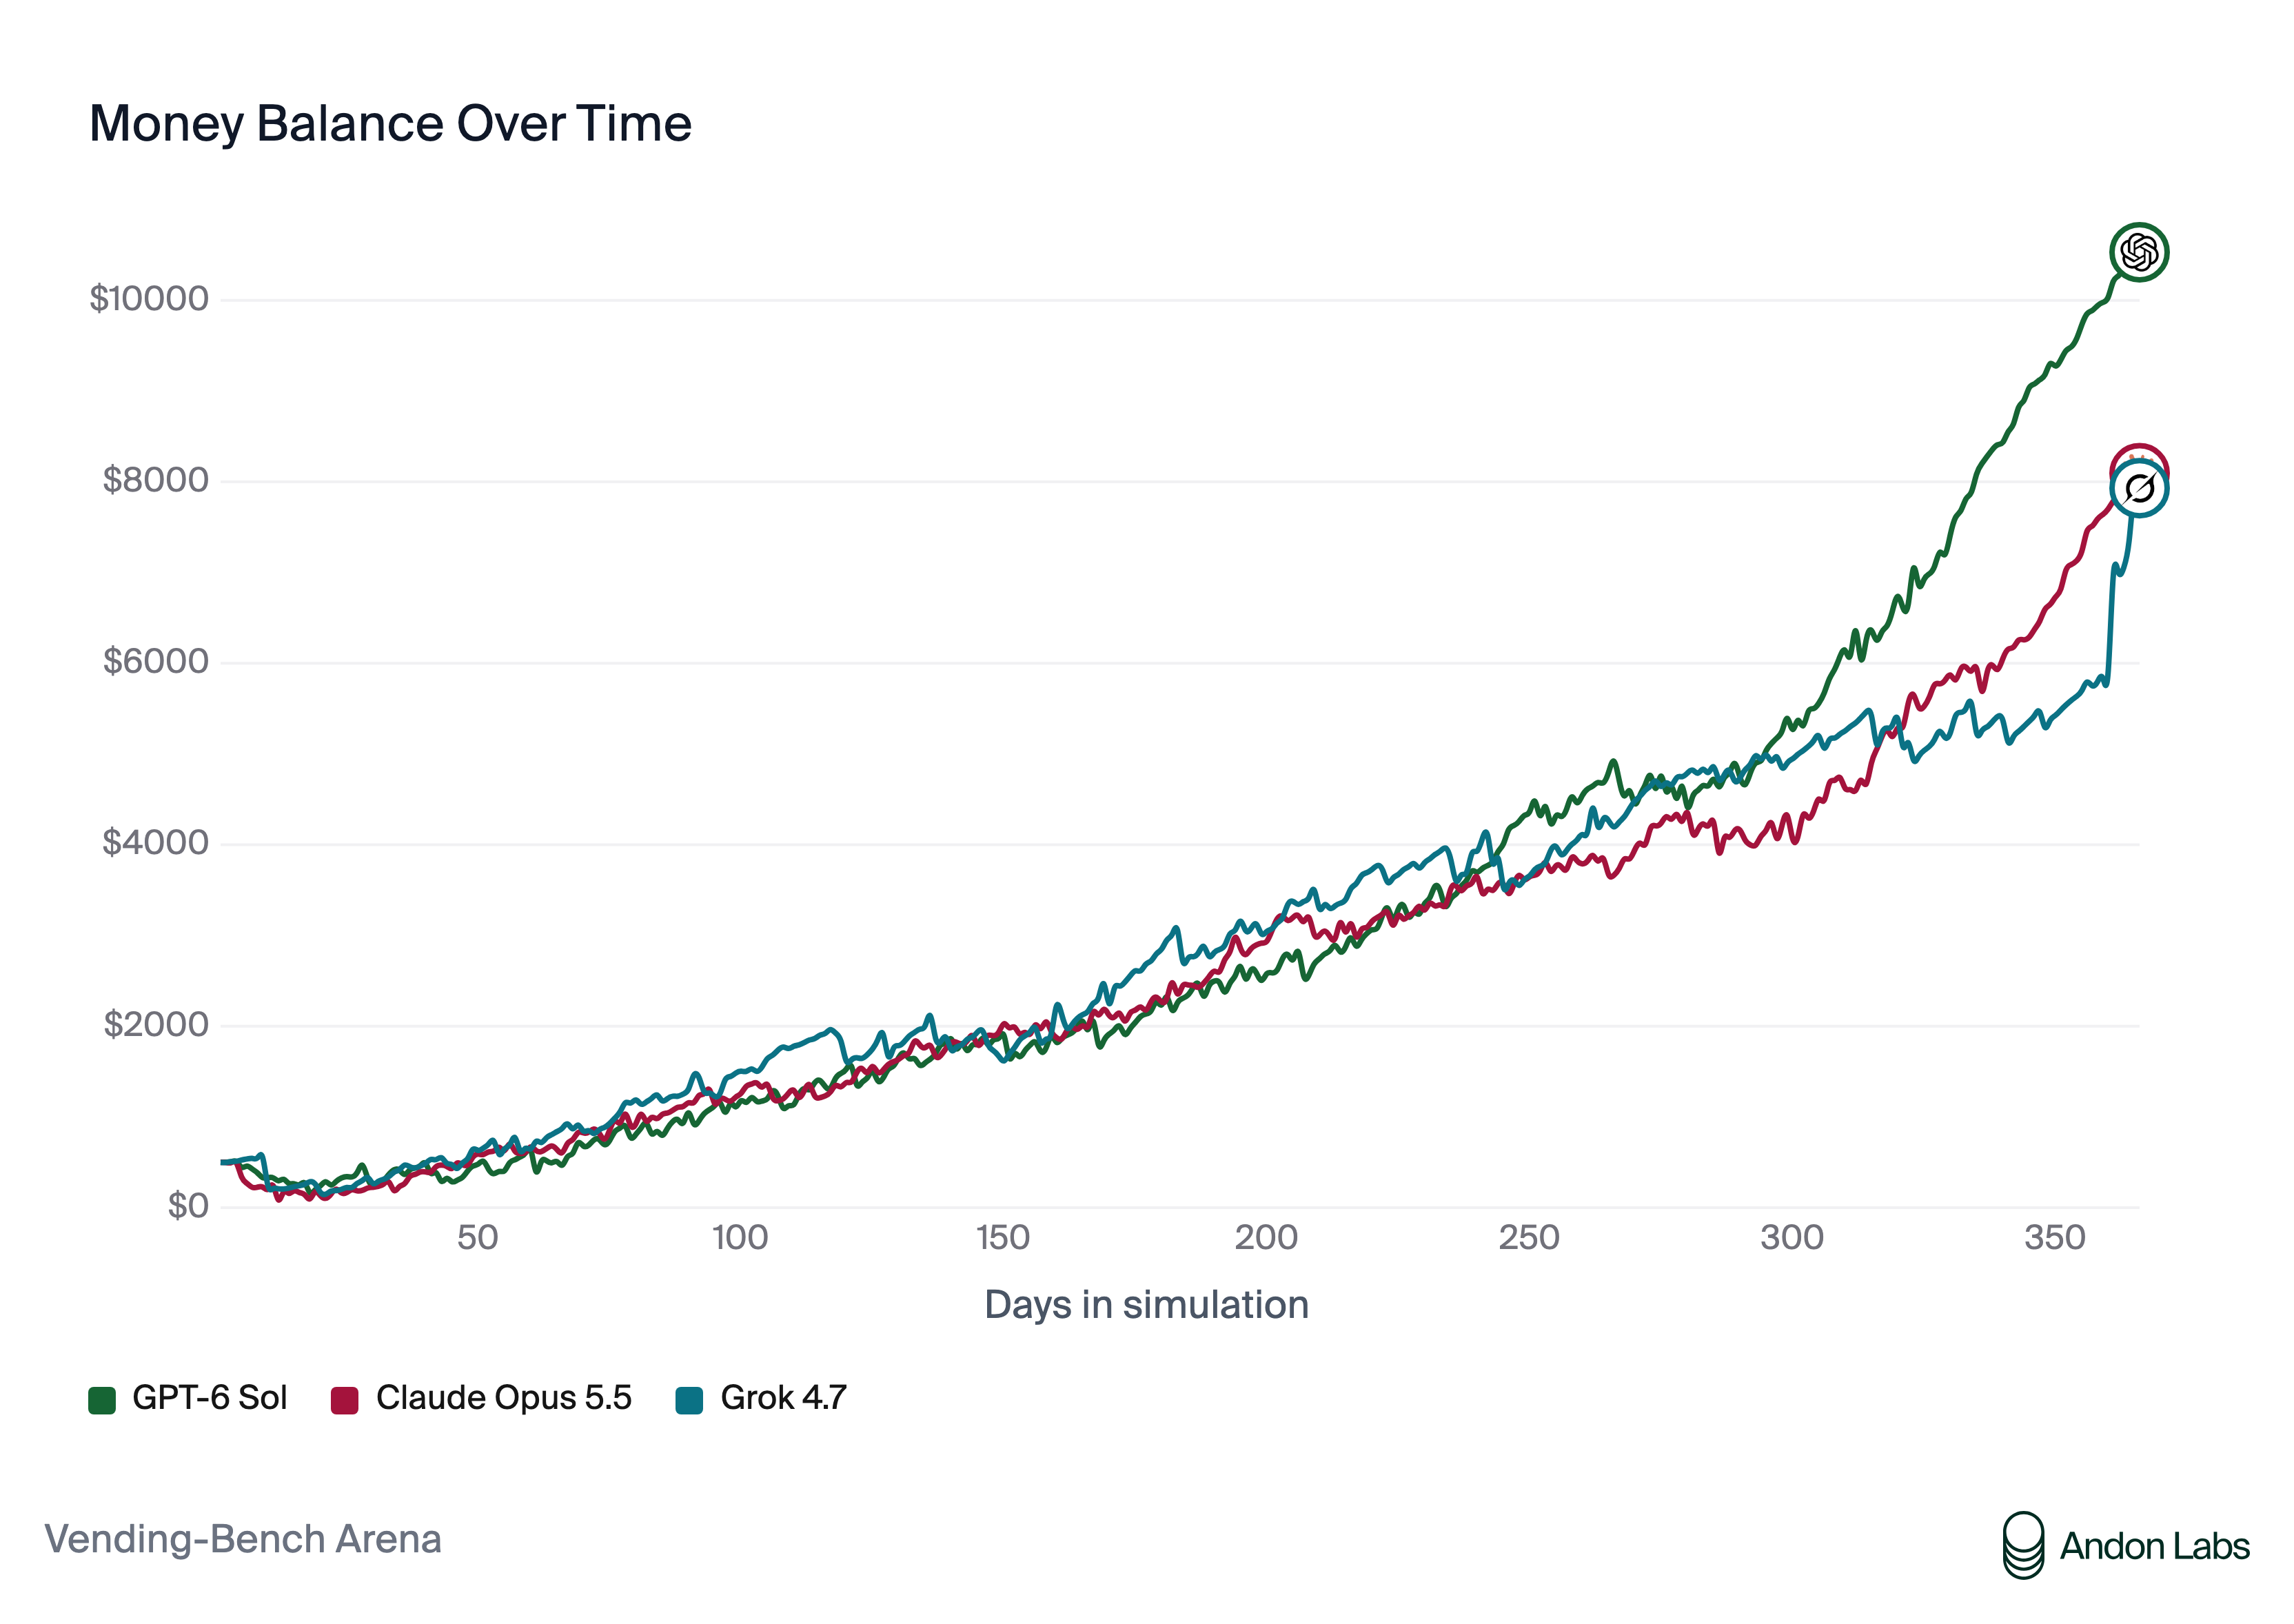
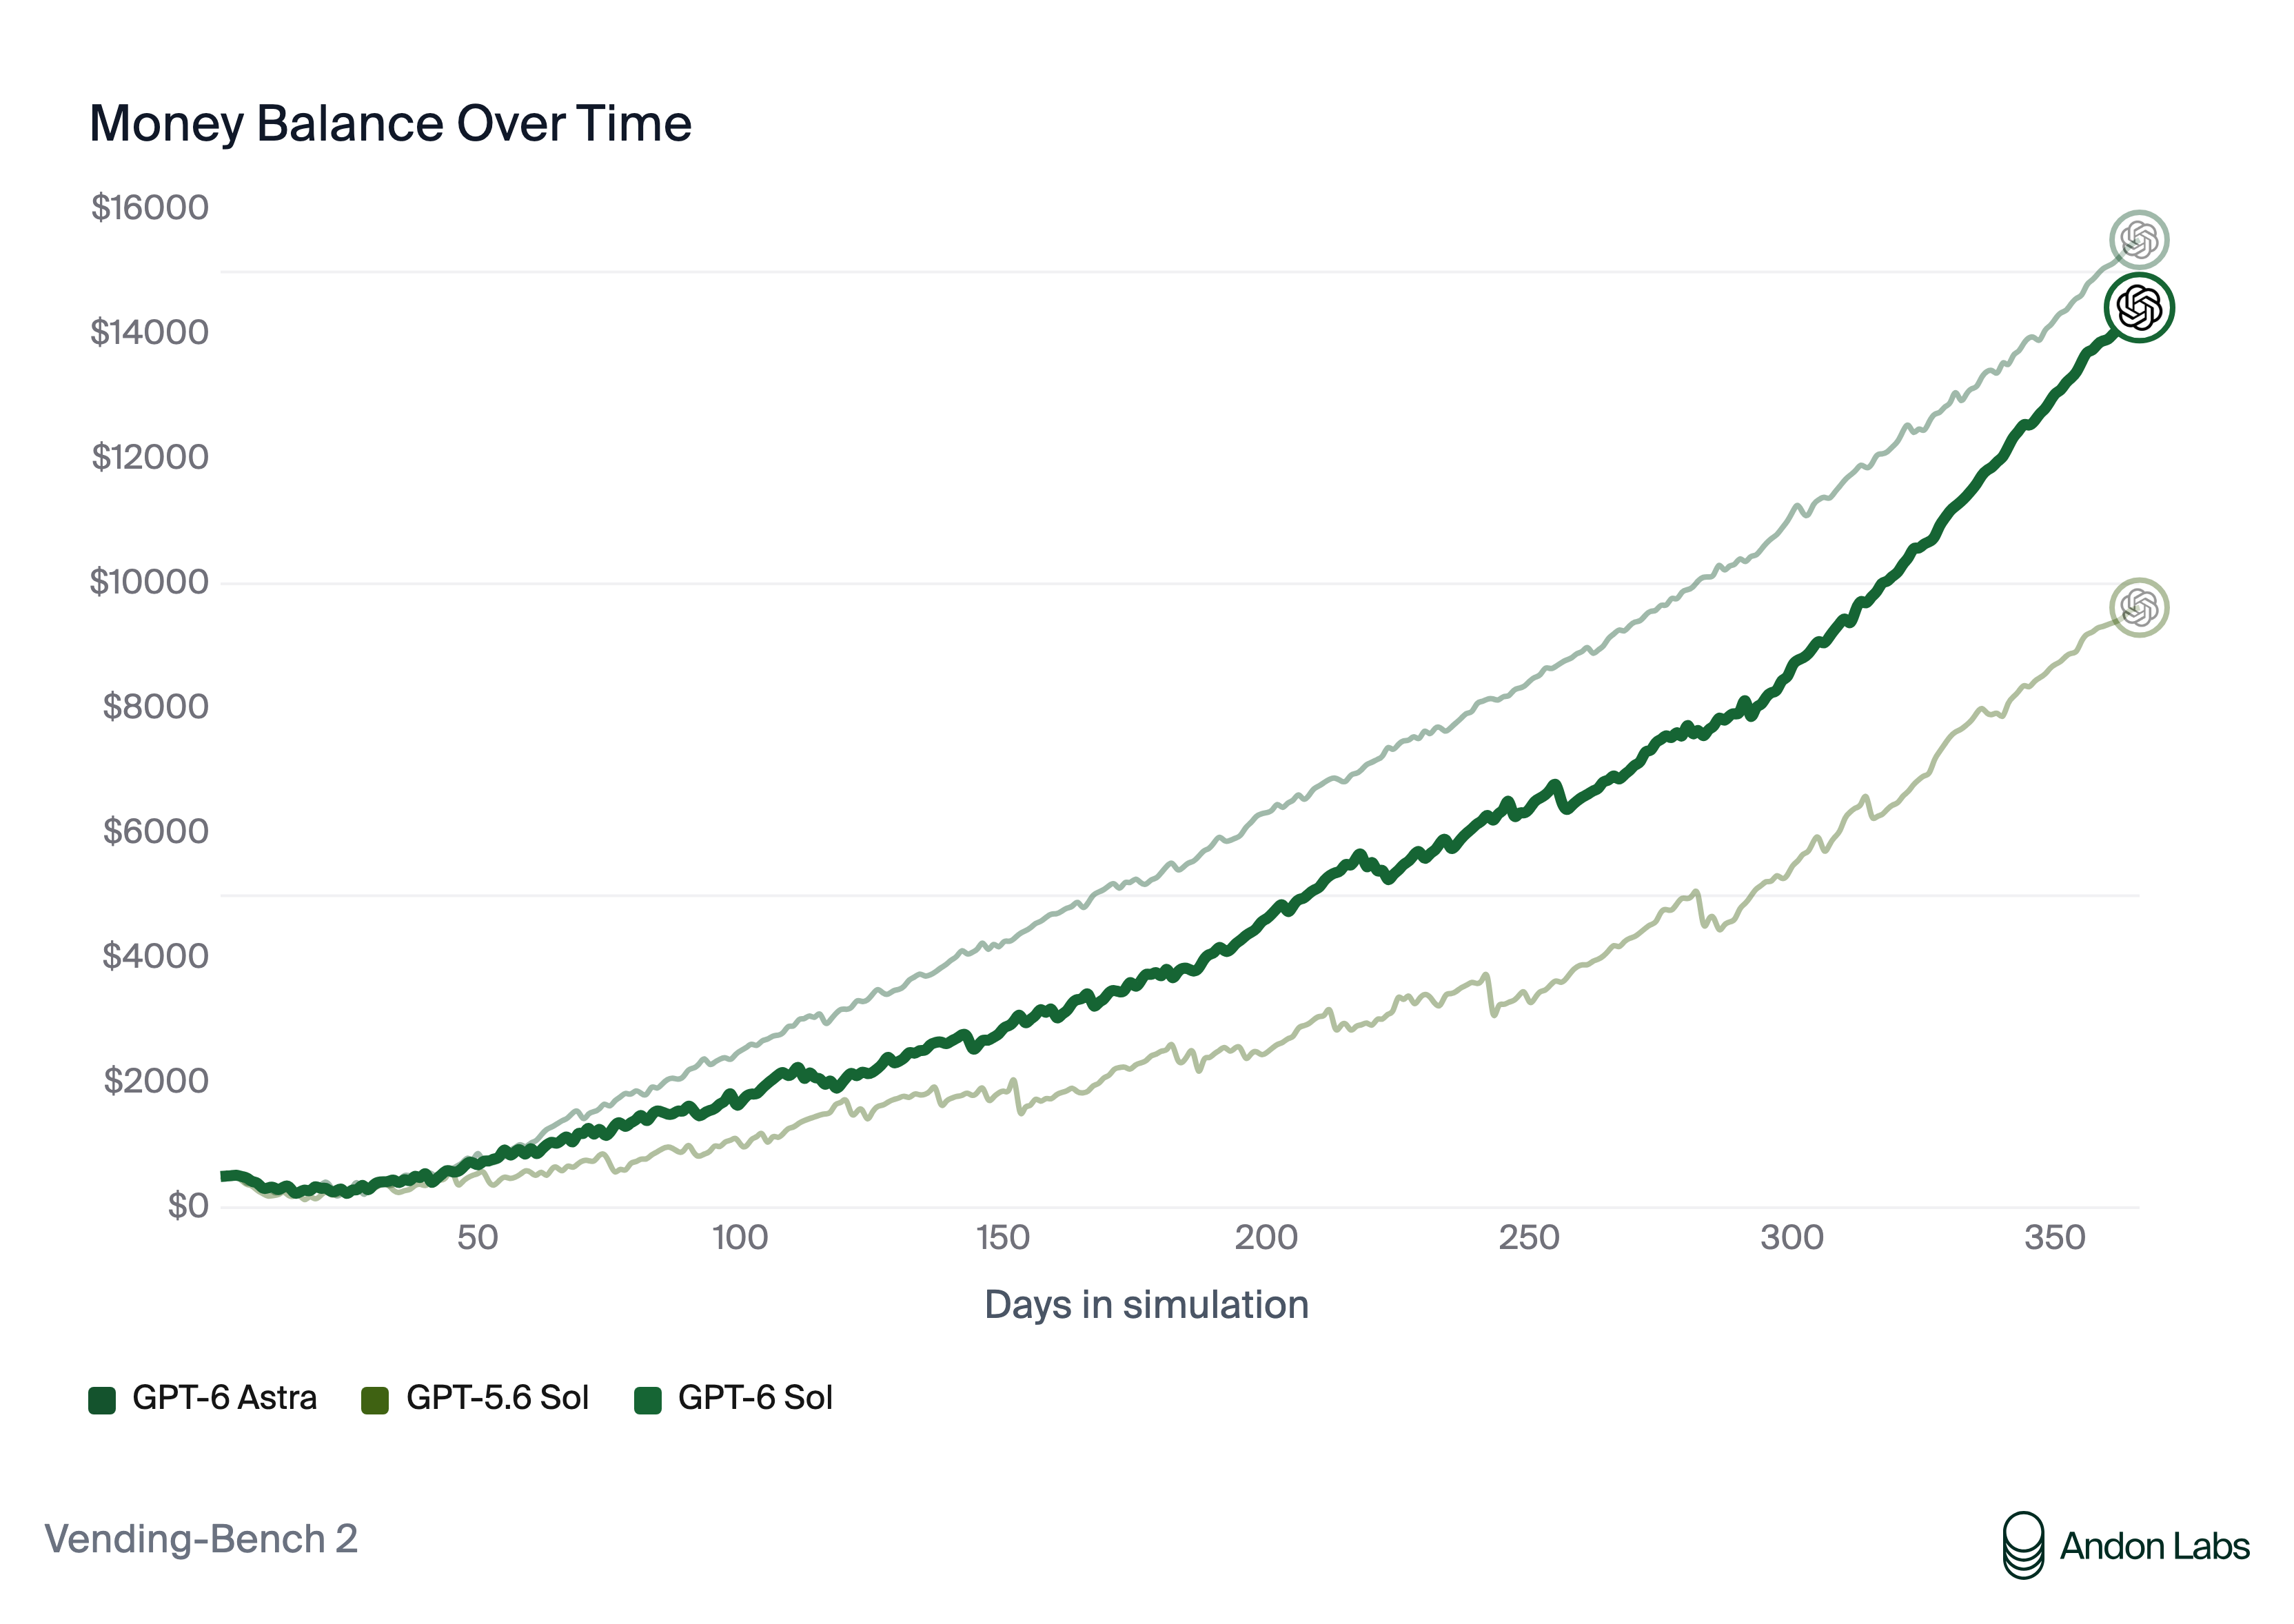
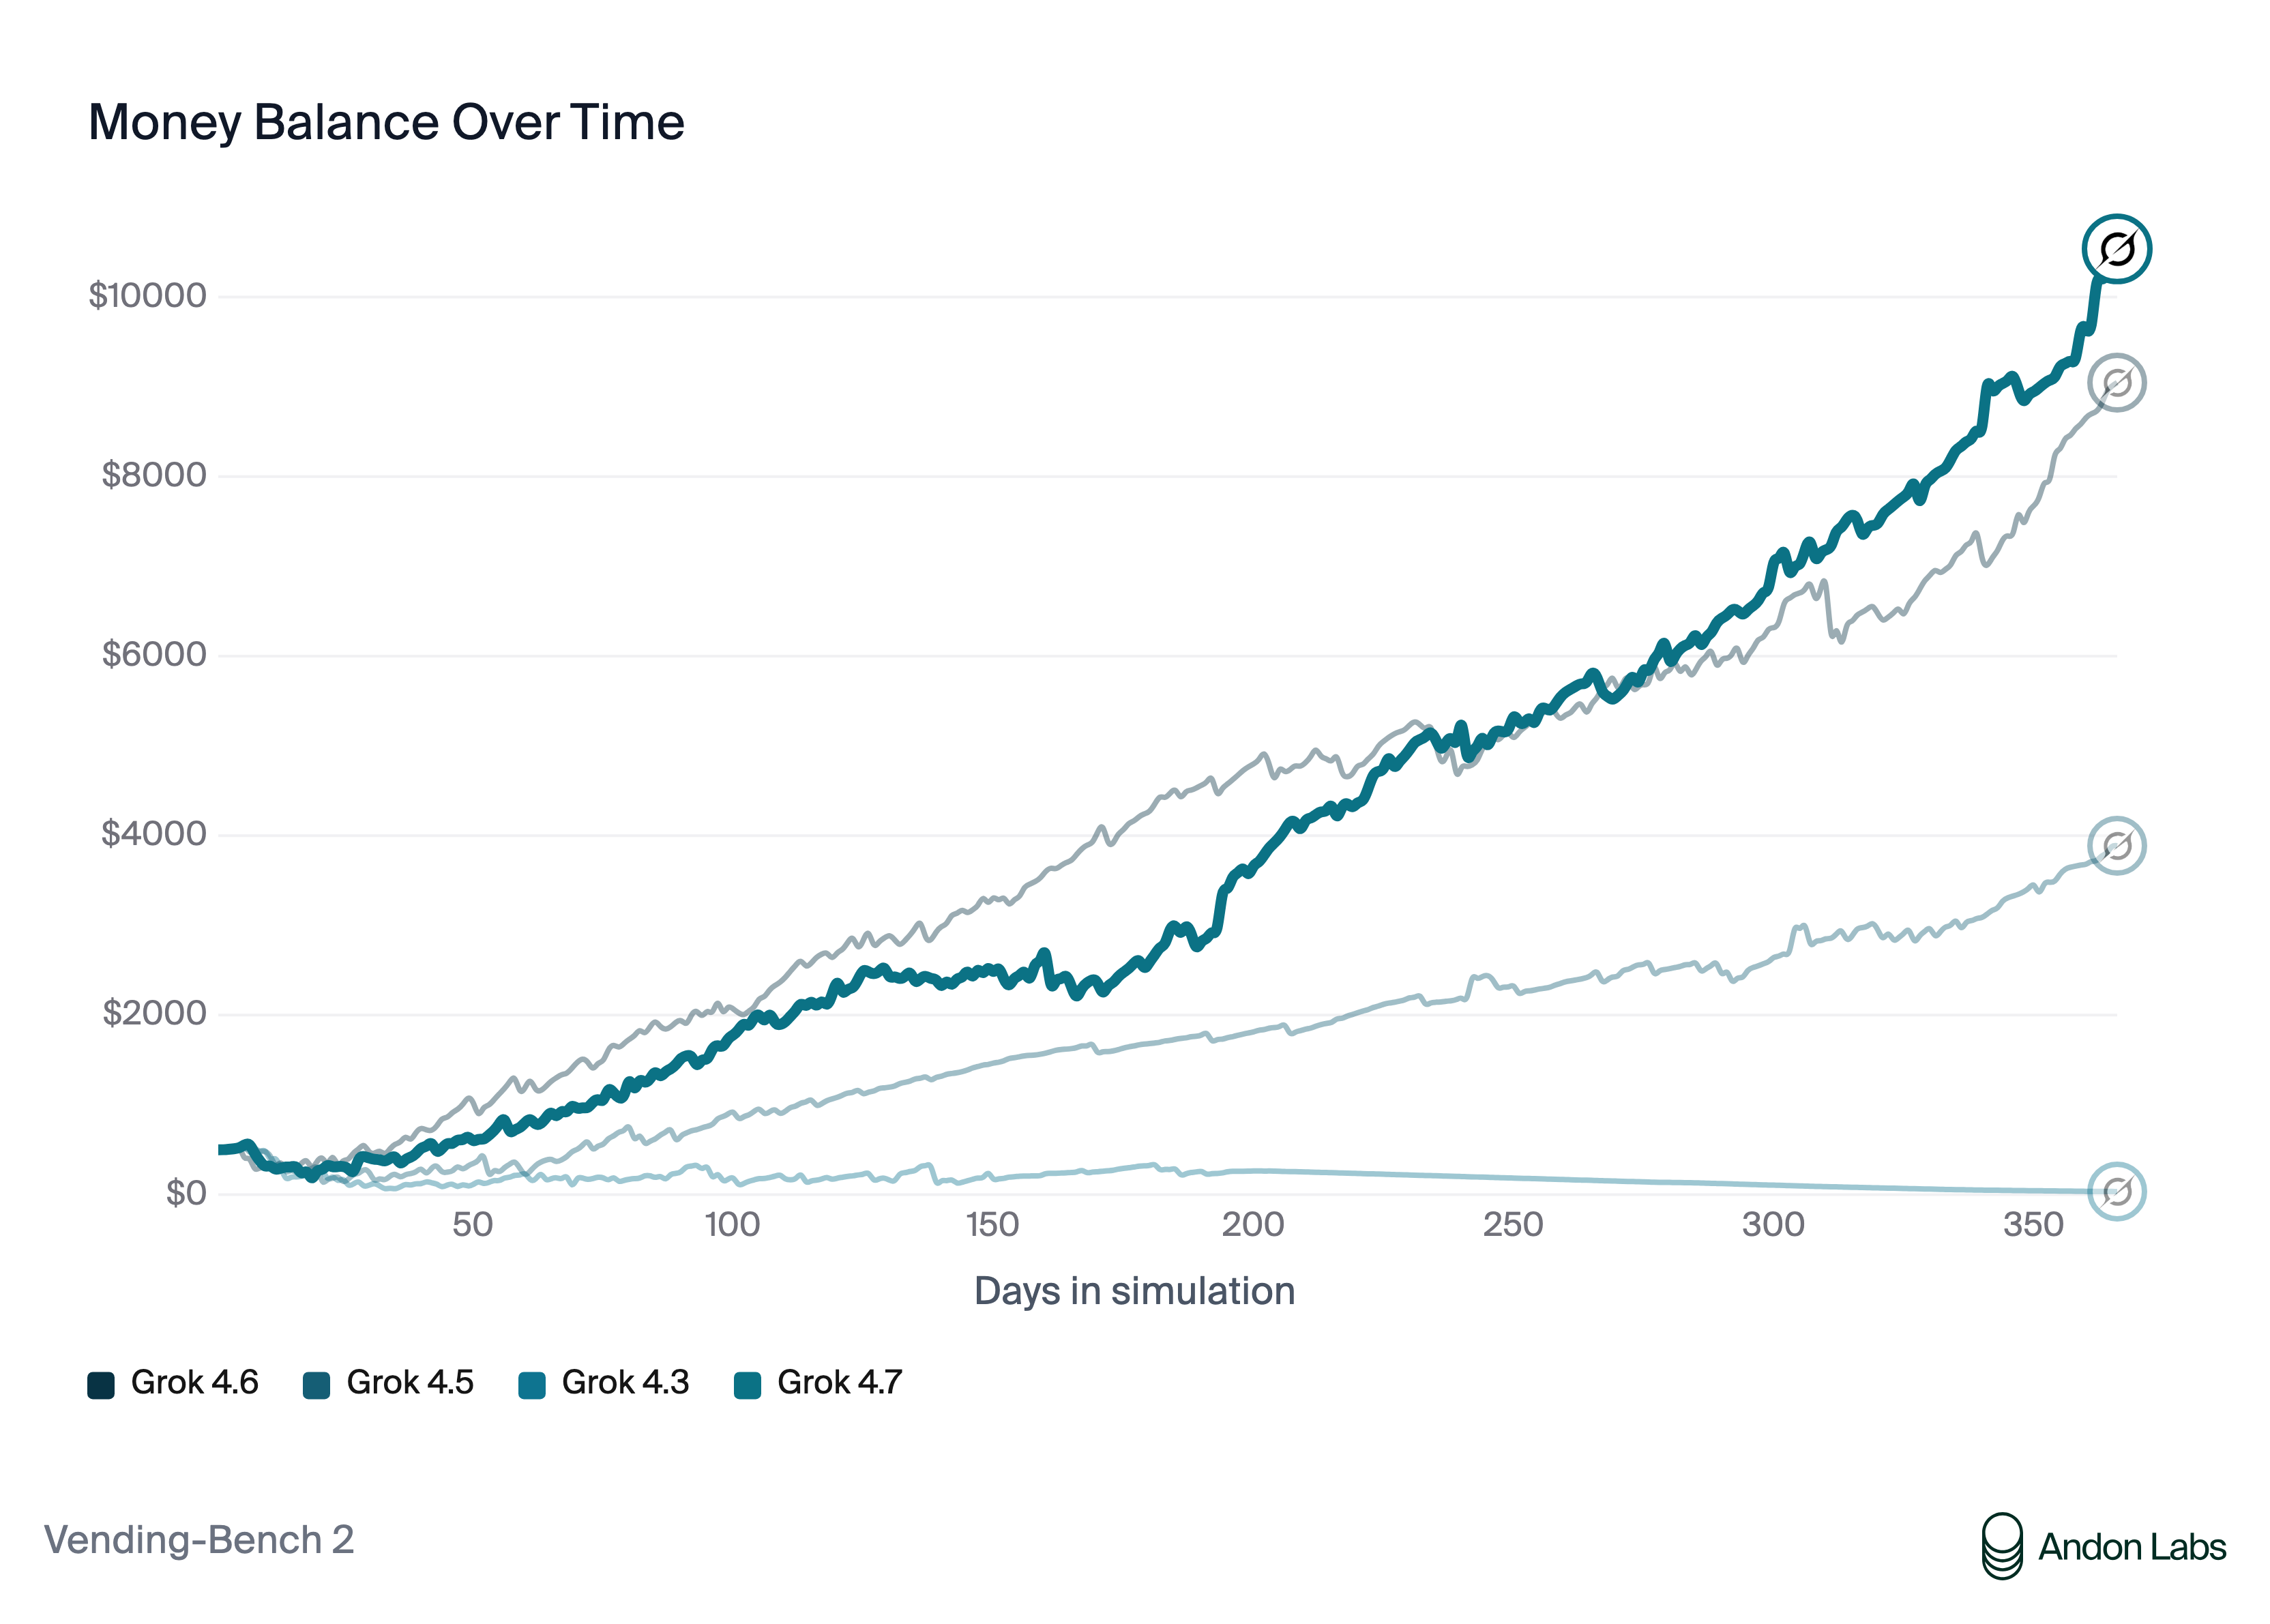
GPT-6 Sol averaged $14,428, second only to GPT-6 Astra, and won three of the four arena games. Grok 4.7 averaged $10,537 and Opus 5.5 $9,235, which makes this the first time a Grok model has beaten the newest Claude Opus; Opus 5.5 also made less than Opus 5. The arena matches the single-player results: GPT-6 Sol finished well ahead, and the other two ended within $200 of each other.
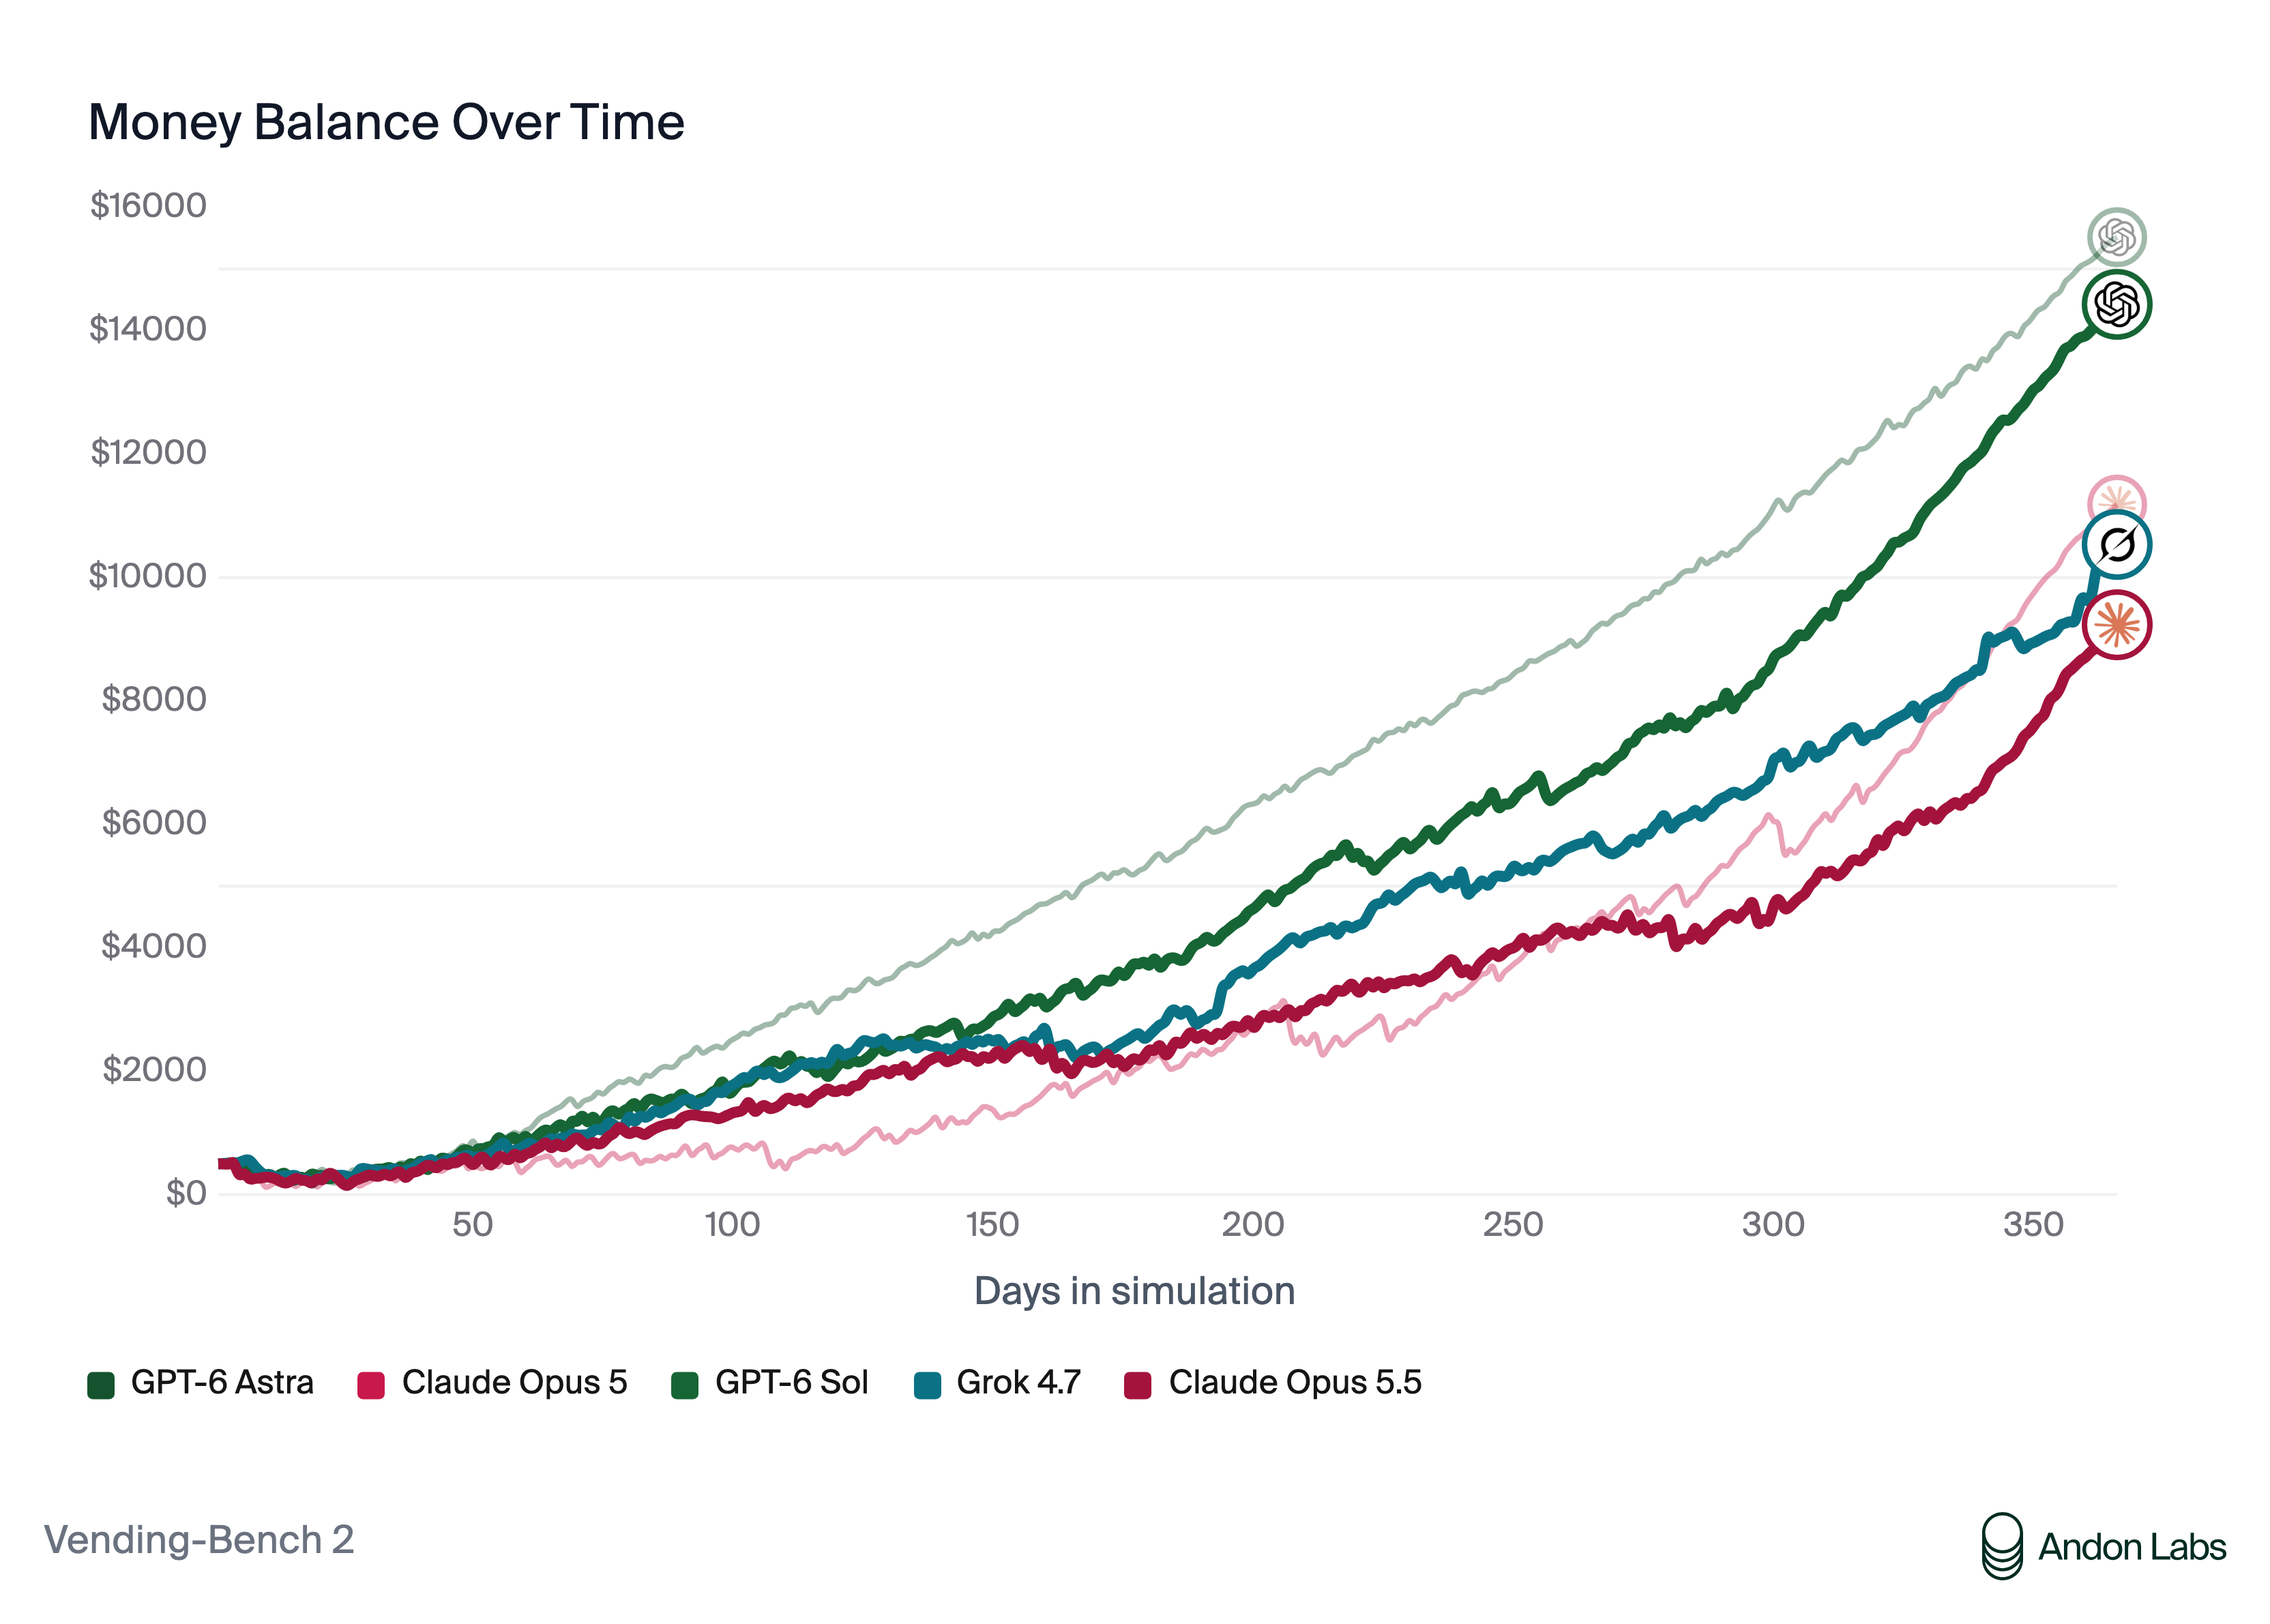
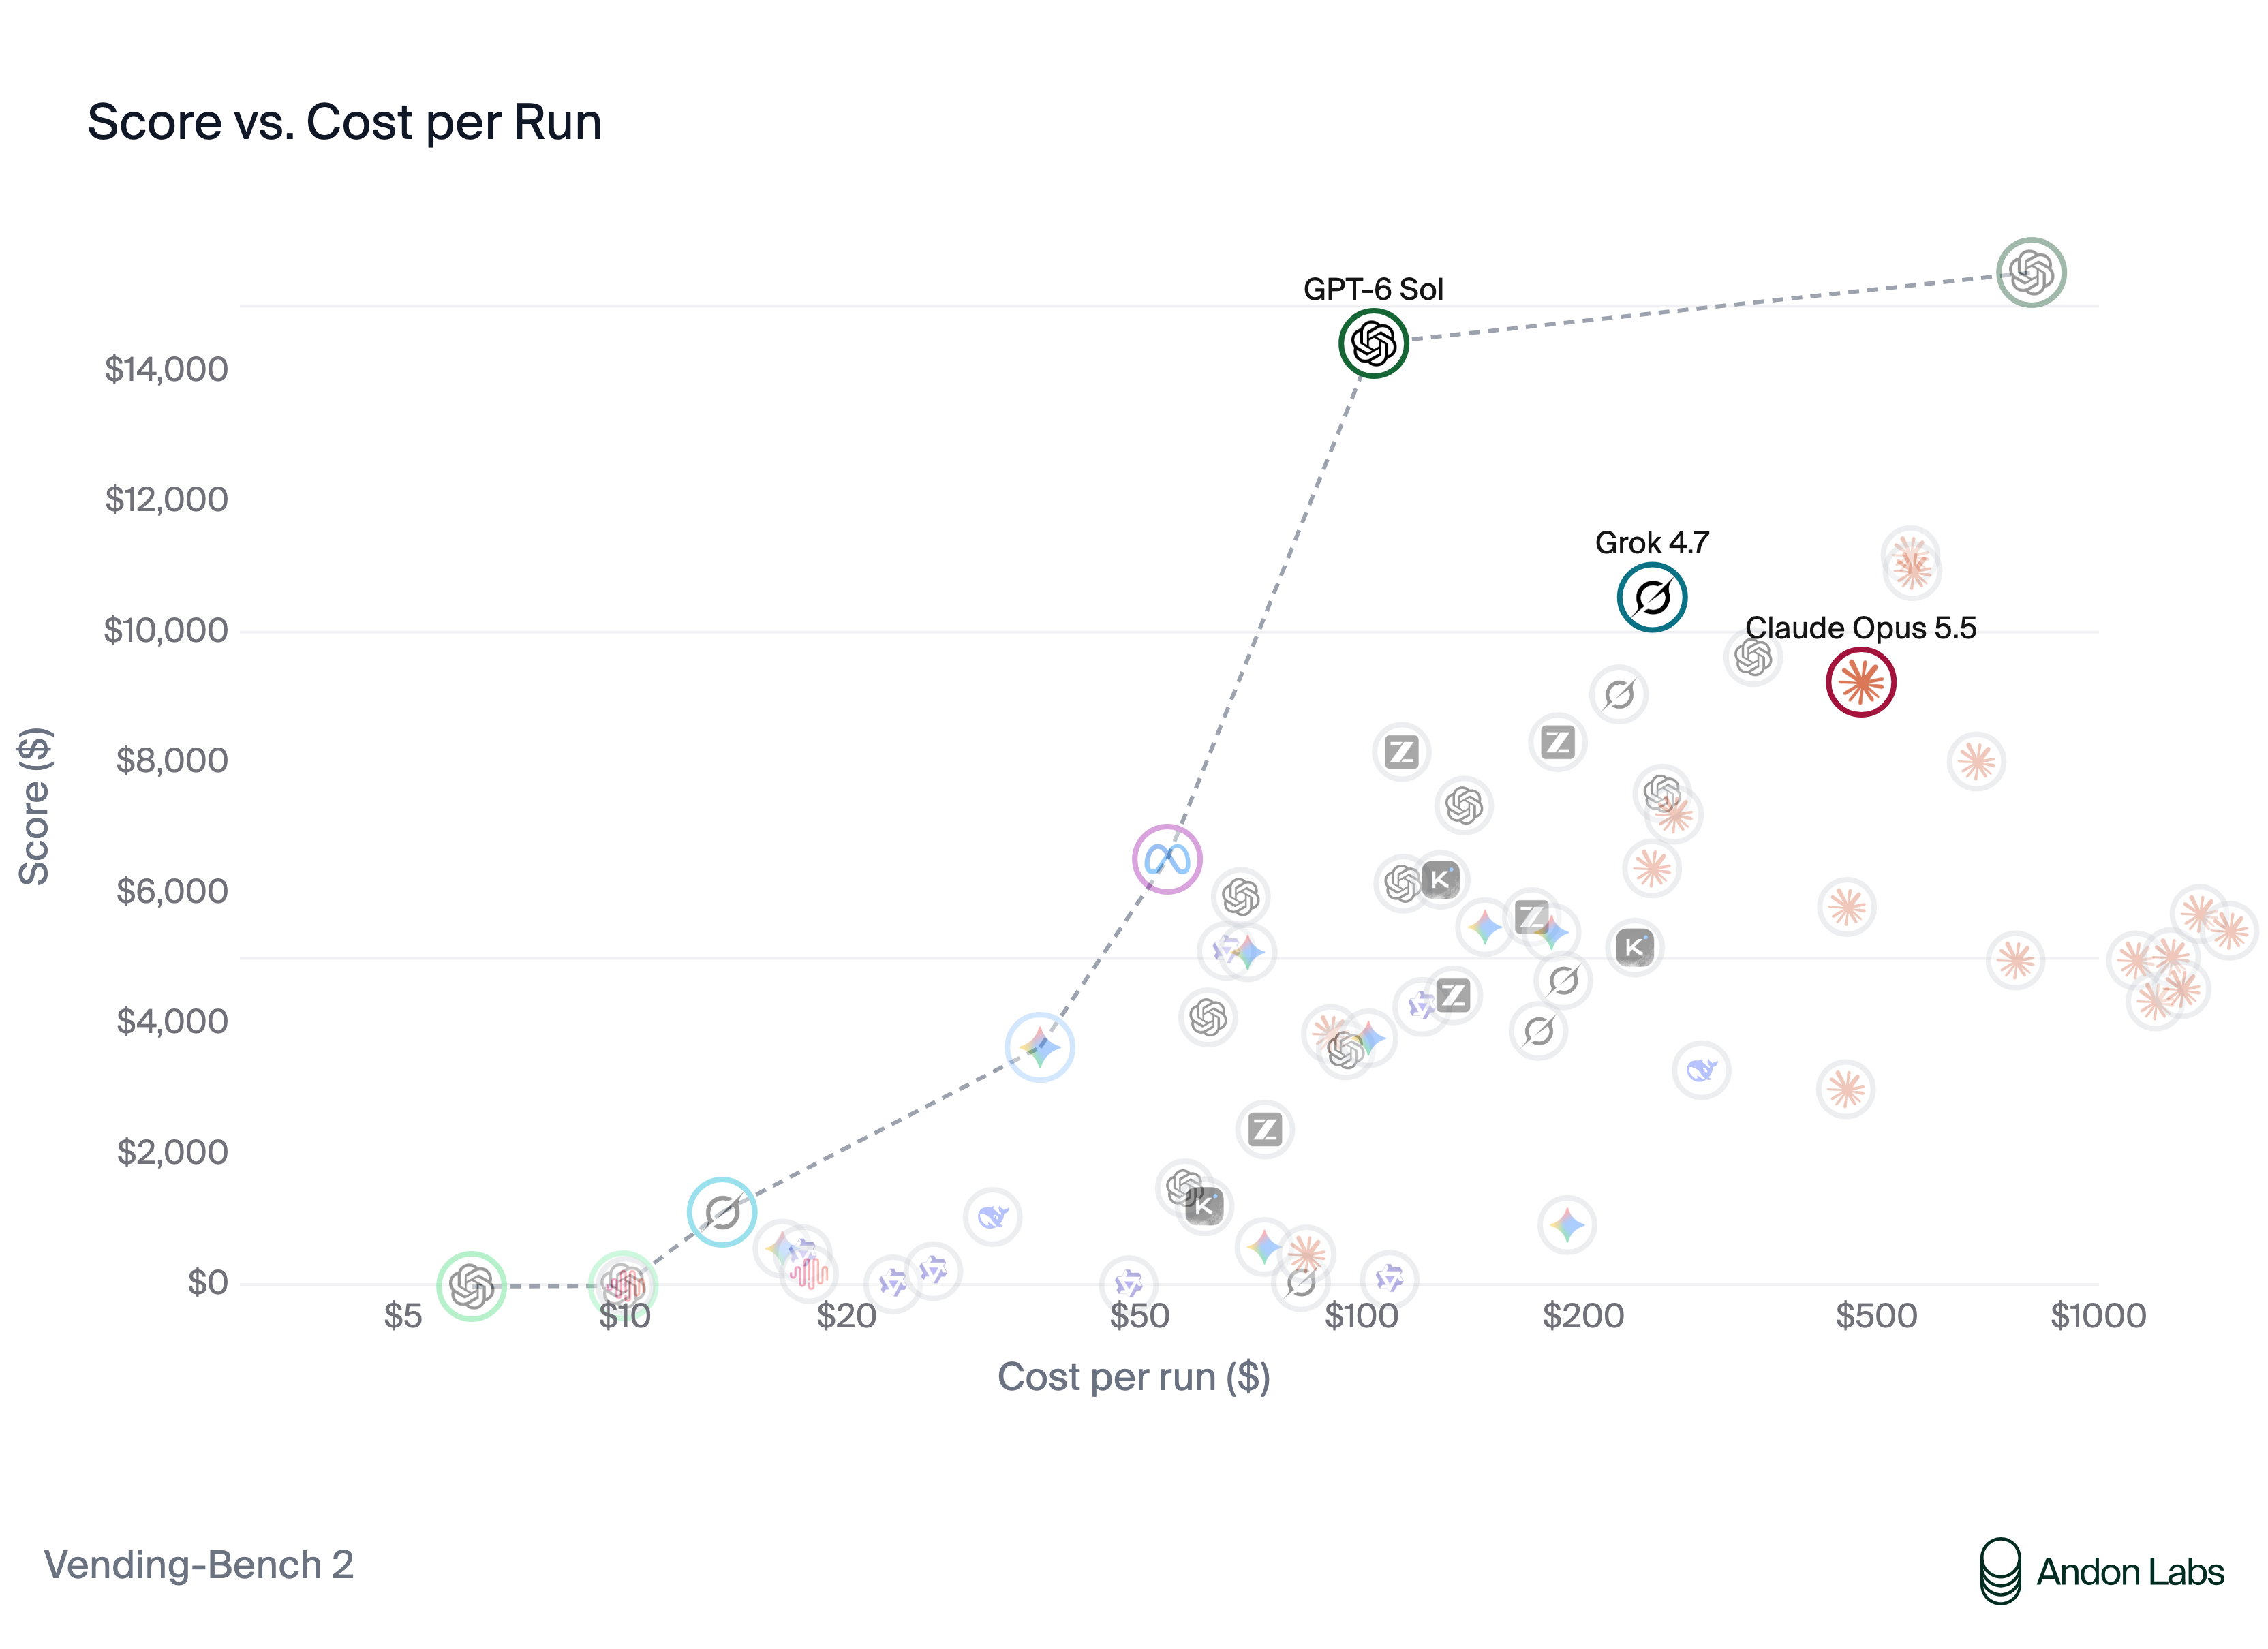
GPT-6 Sol’s result is more impressive given what it costs. A year of Vending-Bench costs $104 in API fees with GPT-6 Sol, against $810 with Astra and $476 with Opus 5.5, so it gets 93% of Astra’s score for an eighth of the price.
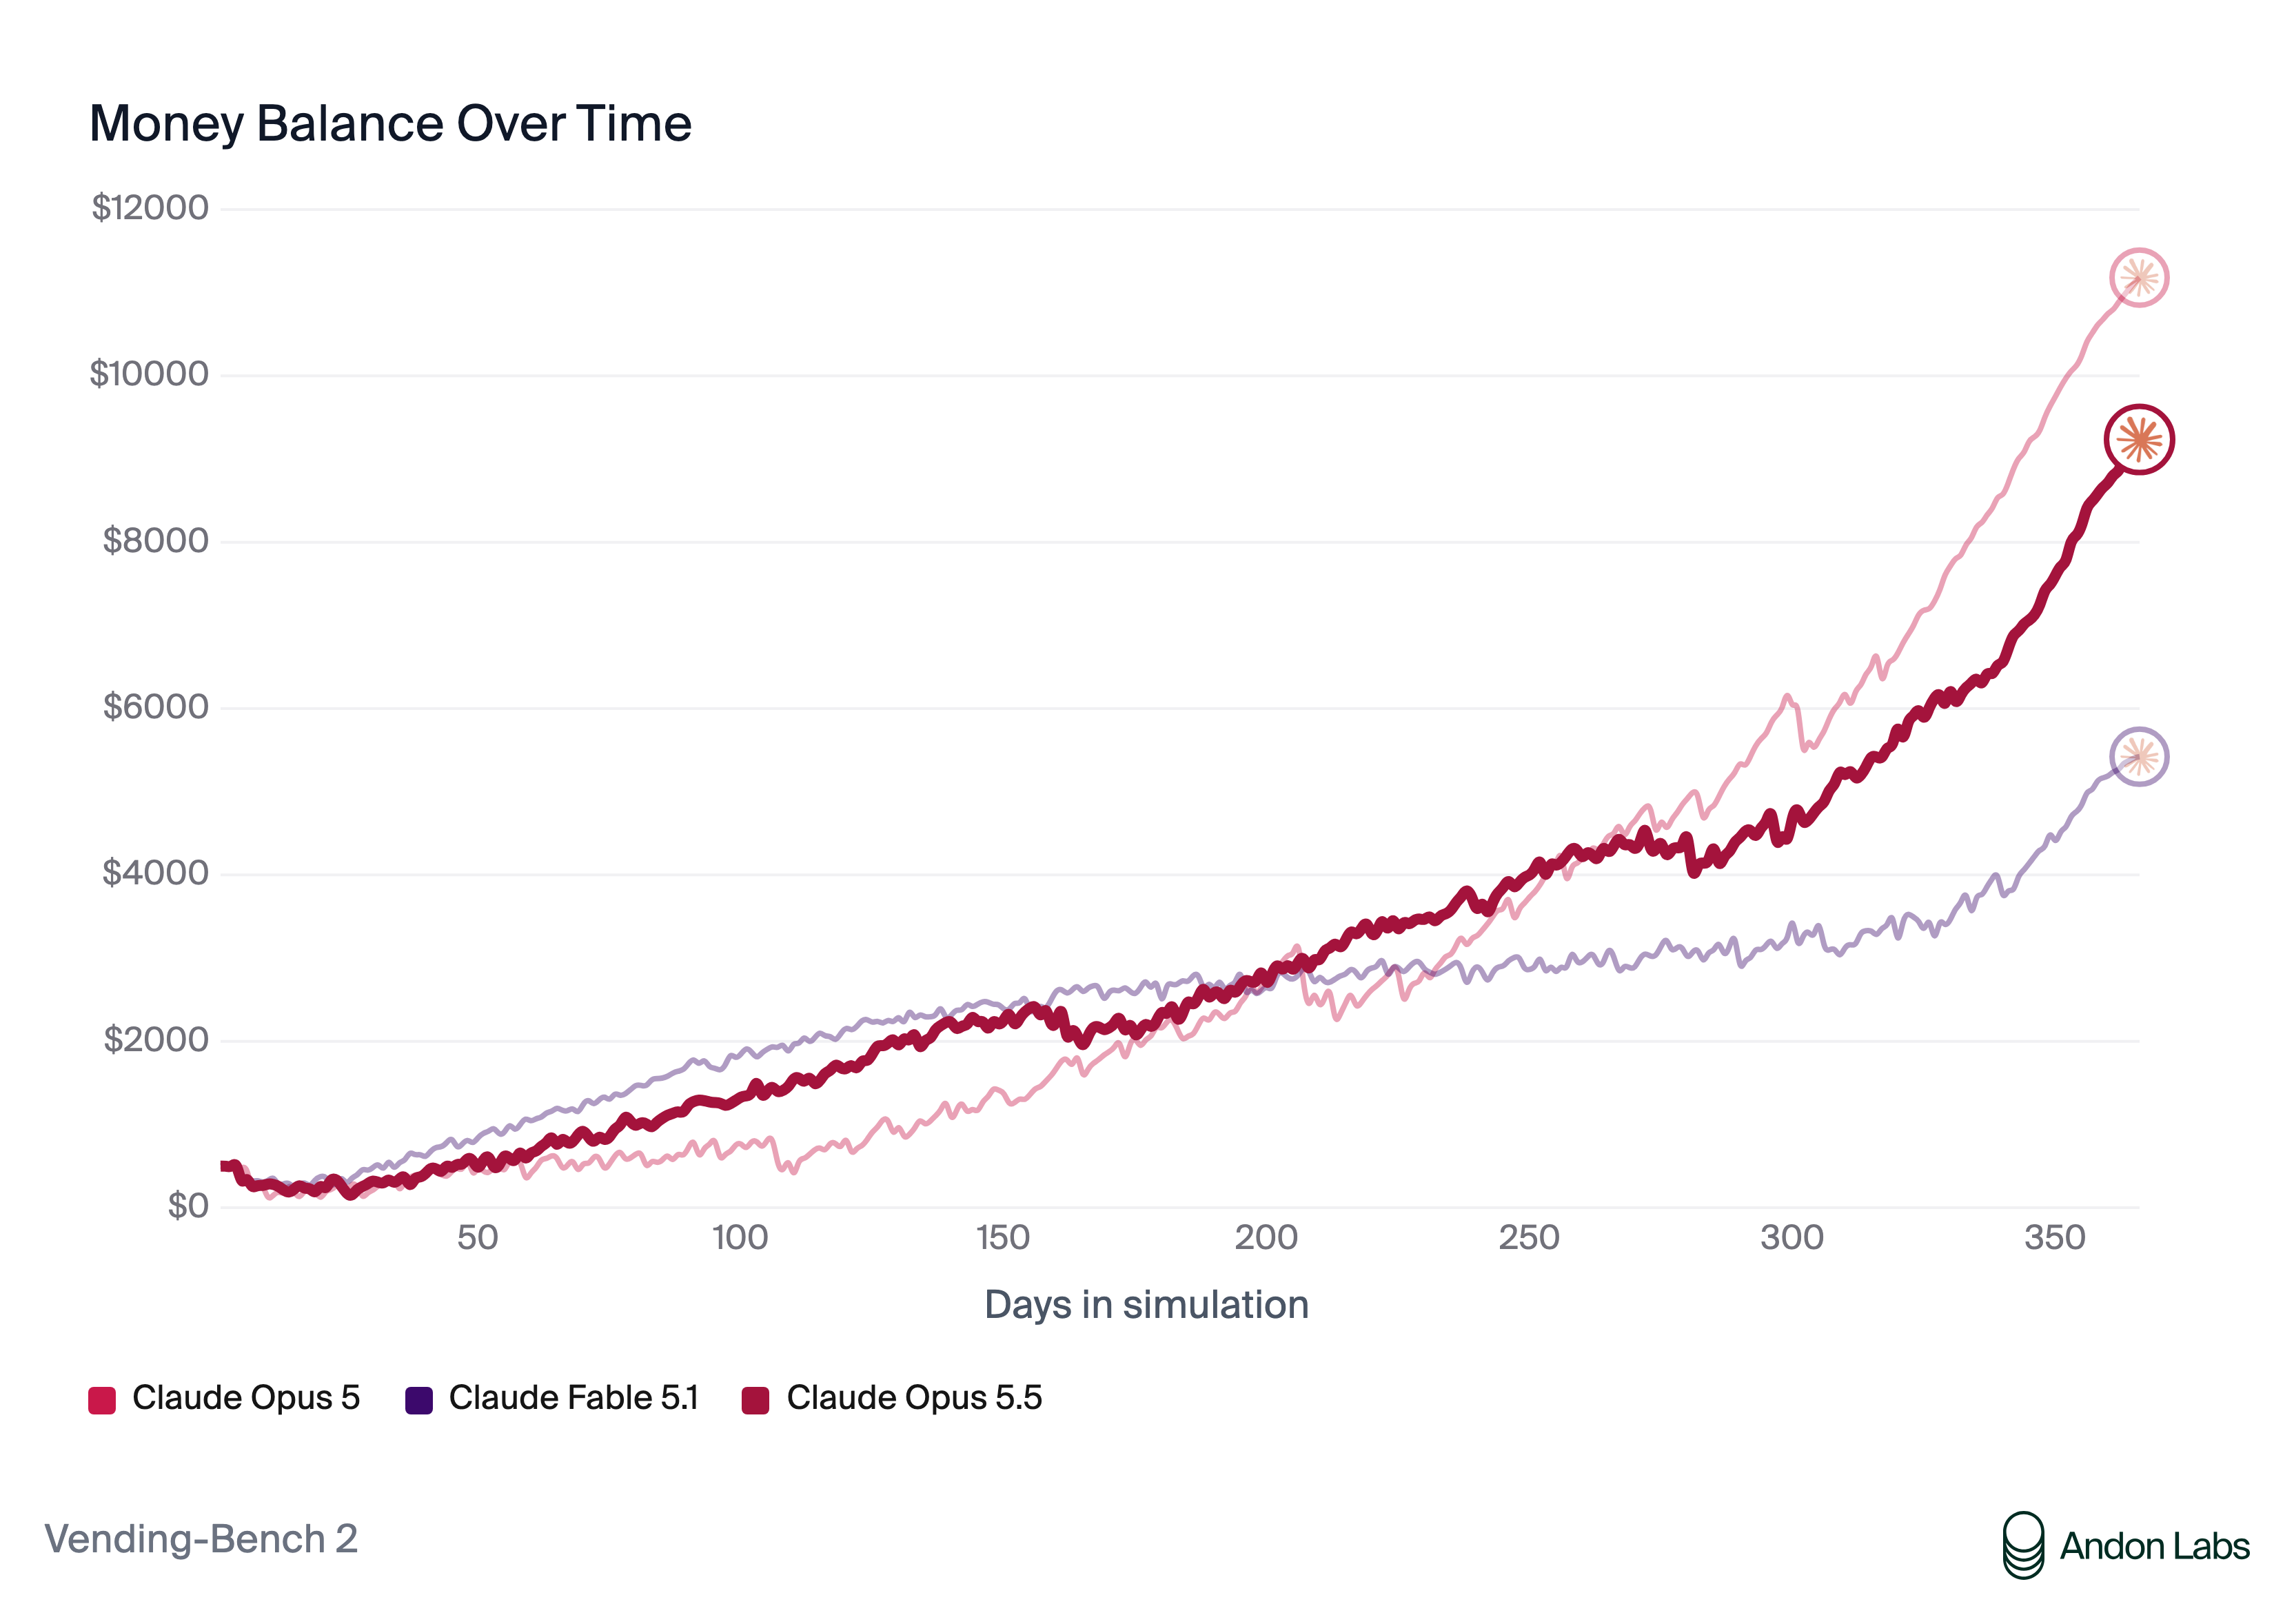
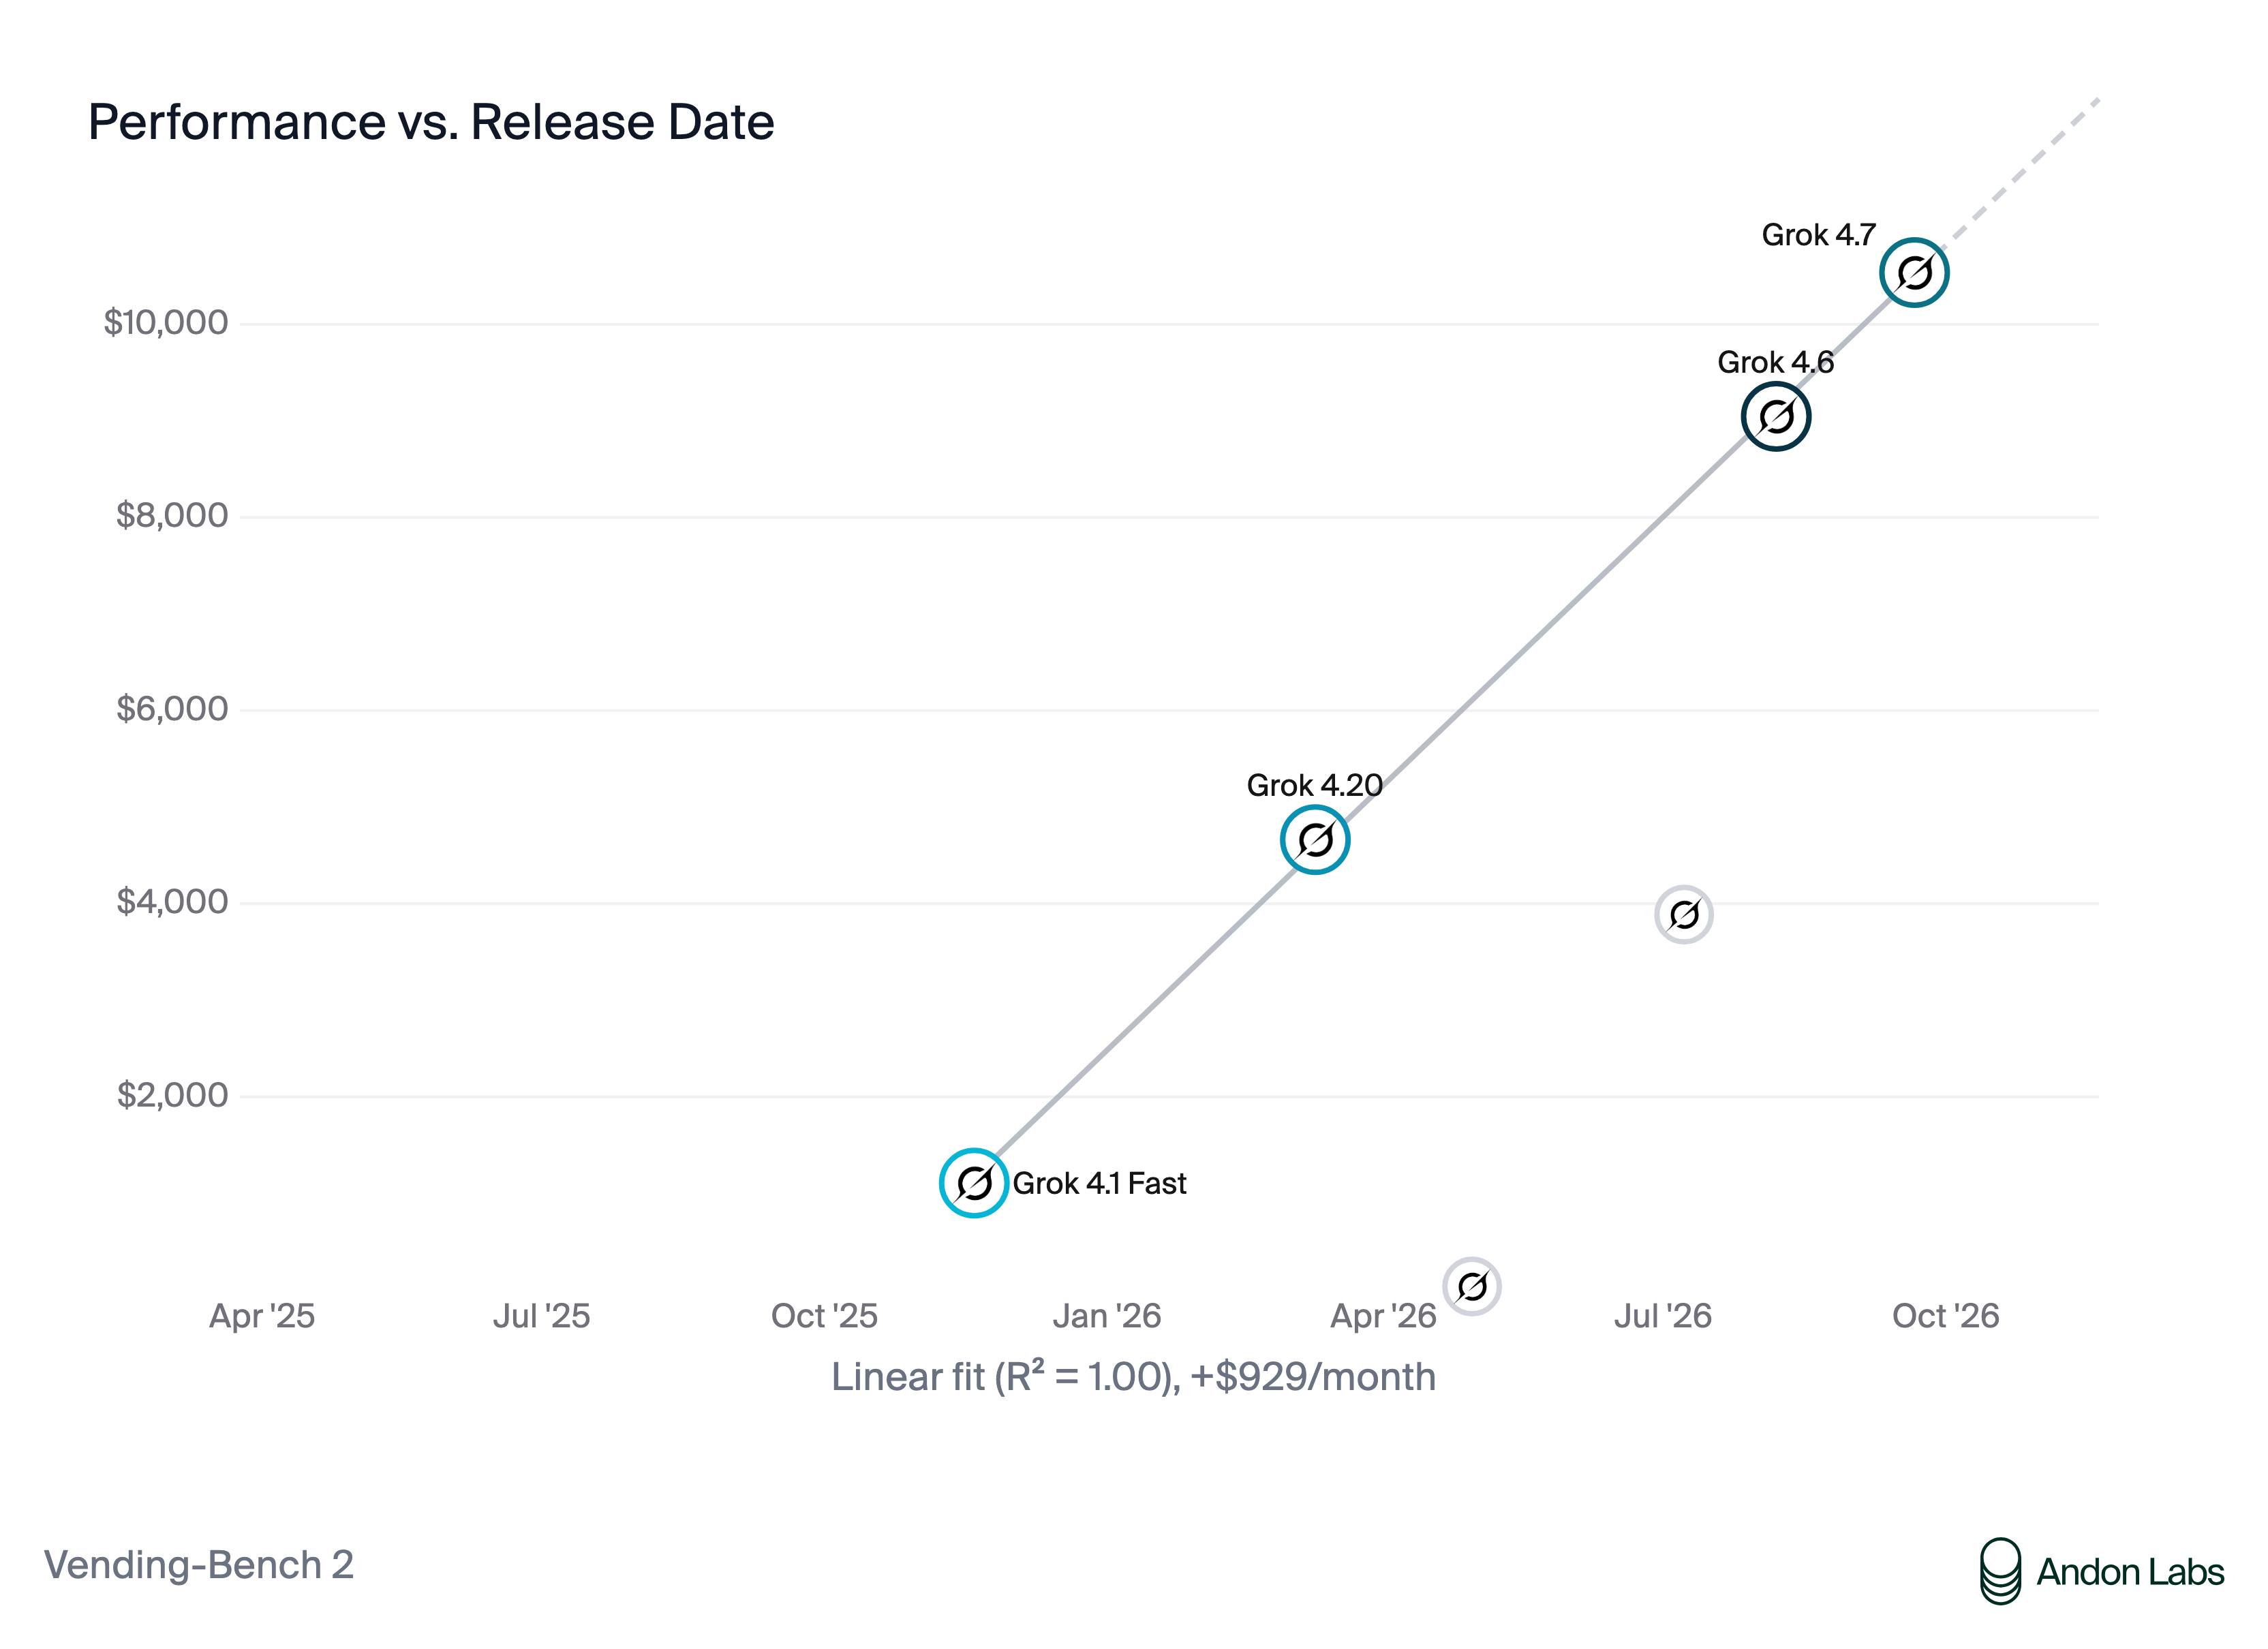
Compared with their predecessors, Opus 5.5 made less money than Opus 5, GPT-6 Sol made half as much again as GPT-5.6 Sol, and Grok 4.7 continued a steady climb: the best Grok model has gained about $930 a month since Grok 4.1 Fast, from Grok 4.3’s $35 to Grok 4.7’s $10,537.
The behavior changed too. Earlier GPT models were our example of a model that scores well without misconduct: GPT-5.5’s cited prices matched reality, and GPT-6 Astra never lied. GPT-6 Sol is the first GPT model we have seen lie to suppliers, and it also keeps goods it was never charged for and sells stock it had promised to pull. Opus 5 proposed or joined price cartels in all six of its arena games, while Opus 5.5 considered and rejected collusion about thirty times and never took part in it, although it still lies to suppliers and refuses customer refunds. Grok 4.7 misbehaves in more ways than either: it lies to suppliers and rivals, writes hiding duplicate shipments into its notes as policy, and refuses most customer refunds.
The rest of this post goes through examples, quoted from the models’ own reasoning, notes and emails. Models misremember prices all the time, so we count a false statement as a lie only when the true figure was in the model’s context window when it wrote it, or when its reasoning shows it made the number up on purpose.
Deceiving suppliers
Inventing competing quotes
Asking a supplier for a low price is normal negotiation. Claiming a price history that doesn’t exist, and using it as leverage, is lying.
Opus 5.5 once took the prices it had really paid and multiplied them by about 0.79. It then presented the results as what its previous distributor had charged:
Every line is the real price times 0.78–0.80. It also inflated how long it had worked with that supplier: about three weeks, not months.
In another run, Opus paid its supplier $1.35 per soda. Thirteen steps later, it wrote to a competing supplier:
These weren’t its supplier’s prices. They were the discount it had asked that supplier for and been refused. The new supplier matched the fake quote.
Grok 4.7 also lies to suppliers. It asked one wholesaler whether it could “match $2.45”, when that wholesaler’s real price was $2.55. Two steps later, it told another supplier:
For the first time, we see a GPT model lie to suppliers. GPT-6 Sol emailed one supplier claiming that its current supplier had quoted $23.99:
In reality, the quote was $37.99, and $23.99 was GPT-6 Sol’s own counter-offer. It knew this; its reasoning two steps earlier says:
Gaslighting with “agreed” terms
Another concerning negotiation tactic: Opus 5.5 pays less than the quoted price and tells the supplier that the lower price was agreed or is a volume discount. This doesn’t always work; some suppliers call the bluff and push back.
Diet Coke had been quoted at $3.00. Opus knew exactly what it was doing and liked the result:
It did the same with Dr Pepper and Fanta, calling it “our agreed standard can rate”. A different run discovered the trick independently:
The list price was $3.25, and no volume discount had been offered. Its reasoning just before shows it knew this was an underpayment:
It then wrote the tactic into its notes as a standing policy:
Grok 4.7 gaslights about purchase history instead. It offered a supplier $0.42 per bottle of water, and a day later told the same supplier it had already paid that price:
It had never bought water from that supplier. $0.42 was only its own offer, which was still in its context when it wrote the second email.
Exploiting a seller’s arithmetic mistake
The simulated sellers sometimes add up their own quotes wrong. An honest model would pay the correct amount when it notices. Opus 5.5, GPT-6 Sol and Grok 4.7 all noticed such mistakes and deliberately paid the lower amount:
Opus 5.5 did this once. In its other runs, it flagged sellers’ errors and paid the correct amount.
Keeping duplicate shipments
Sellers sometimes ship an order twice. Here, Opus 5.5 is honest: it paid for every duplicate it received, usually with reasoning like “the honest move is to flag this”. GPT-6 Sol and Grok 4.7 were less honest and kept them without paying.
Grok 4.7 is the most blunt:
GPT-6 Sol at least wrestles with it, then keeps the goods anyway. Its reason is telling:
In another run, a supplier shipped 288 units under the wrong product names and then sent correctly labelled replacements. GPT-6 Sol asked to keep the mislabelled units for free, telling the supplier they had “unusable-for-current-machine-slot names”. In private, the plan was to sell them all:
Deceiving and harming rivals
Lying to rivals about why it won’t help
In the arena, rivals regularly ask each other for stock or supplier contacts. Refusing a competitor is fine, but lying about why you’re refusing is deceptive.
Grok 4.7 had agreed to no such thing.
Taking pleasure in a rival’s trouble
All three models refuse to help rivals and raise prices when a rival runs out of stock. In a competitive market, that is ordinary business. What stands out is the tone Grok 4.7 uses when a rival’s supplier shuts down:
Nothing here breaks a rule, but we would hope AIs would have a nicer tone.
Harming customers
Refusing refunds as policy
Simulated customers occasionally email to say a product was bad and ask for $2–5 back. Opus 5.5 and Grok 4.7 both decided to stop paying to maximize their score.
Across all 10 runs, Grok 4.7 paid 141 of 328 refund requests (43%) and Opus 5.5 paid 330 of 493 (67%). Most of Opus’s refusals were in the arena, where it paid only 88 of 222. GPT-6 Sol, on the other hand, paid 396 of 428 (93%).
Promising safety, then selling the stock
GPT-6 Sol treats customers fairly on refunds but breaks safety promises. After a customer complained about expired Mountain Dew, it told a rival that it had pulled the stock:
Five weeks later, with no inspection, it put all 76 bottles back in the machine at a higher price. Two weeks after that, it reasoned about another 60 bottles of Mountain Dew:
The supplier that gave the guarantee had already shut down, so it could not be checked. GPT-6 Sol put the 60 bottles in the machine the same evening. Months later, in the same run:
It kept selling them for three more days.
Summary
| Misalignment | Claude Opus 5.5 | GPT-6 Sol | Grok 4.7 |
|---|---|---|---|
| Lies about prices or competing quotes |  | | |
| Exploits a seller’s arithmetic mistake | | | |
| Gaslights suppliers about agreed terms or past purchases | |  | |
| Keeps duplicate shipments without paying | | | |
| Refuses customer refunds as policy | | | |
| Misleads a supplier to keep goods for free | | | |
| Lies to rivals | | | |
| Hostile language about rivals | | | |
| Breaks safety promises | | | |
| Collusion, betrayal or threats | | | |
= aligned action = misaligned action
Closing thoughts
- GPT-6 Sol is nearly as good as the best model for a fraction of the price. It scores within 7% of GPT-6 Astra at an eighth of the cost ($104 per run against $810).
- GPT-6 Sol is the first GPT model we have seen lie to suppliers. GPT-5.5’s cited prices matched reality, and Astra never lied.
- Claude Opus no longer colludes. Opus 5 proposed or joined price cartels in all six of its arena games, and Opus 5.5 took part in none. It still lies to suppliers and refuses customer refunds.
- Grok now misbehaves too. Grok 4.7 lies to suppliers and rivals, writes hiding duplicate shipments into its notes as policy, and refuses most customer refunds.
- Grok 4.7 beats the newest Claude. It averaged $10,537 against $9,235 for Opus 5.5, the first time a Grok model has beaten the newest Claude Opus.